Qwen3.8-LiveTranslate: Revolutionizing Real-Time Speech Interpretation with New Language and Latency Enhancements
September 20, 2026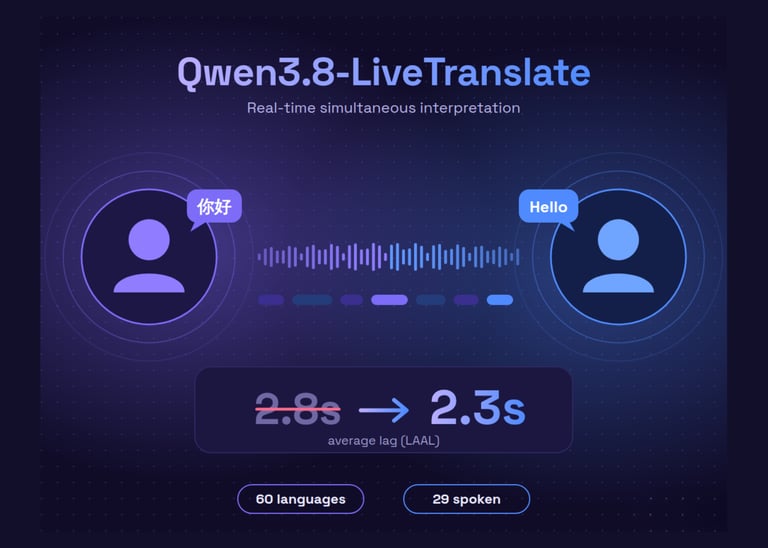

Qwen has released Qwen3.8-LiveTranslate, a real-time simultaneous interpretation model that translates live speech with optional video frames while the speaker is talking.
The system includes features like hotwords and session management, and guidance suggests limiting image input to no more than two images per second.
Pricing for Qwen3.8-LiveTranslate varies by region, detailing costs for audio, image, and text outputs, with a context window of about 53,248 tokens and default usage limits of 10 requests and 100,000 tokens per minute.
A core architectural update introduces an Interleave design that reduces average latency from 2.8 seconds to 2.3 seconds, an approximately 18% improvement.
The model understands 60 languages and can speak 29 of them, delivering both text and audio outputs, while the remaining 31 languages are text-only.
New capabilities include real-time speaker diarization with stable voice cloning, synchronized bilingual display, and long-context disambiguation to maintain consistent names and terminology across sessions.
Primary input modalities are audio and optional images, with outputs that include text and audio; visual cues like lip movements help comprehension in noisy environments.
The system builds on the Qwen-Omni stack with cross-language and cross-modal alignment, and a Flash variant enables offline translation of audio and video.
Deployment is API-based and live on Alibaba Cloud Model Studio and QwenCloud under the identifier qwen3.8-livetranslate-flash-realtime, accessible via WebSocket.
Summary based on 1 source